I literally laughed out loud reading the headline. Good shit, hopefully the Find Out season will carry on at this kinda pace. Probably won’t, but it’d be nice to see.
A German regional court has ruled that Google is directly liable for false claims in its AI-generated search overviews.
Unfortunately, the regional court is the lowest court stage. This will climb up until highest German court and after this to the EU court, I expect to see.
Being then a „Grundsatzurteil“ that is leading all courts in Germany. Our legal system isn’t case driven.
Unfortunately, the regional court is the lowest court stage
No. Landgericht is the second stage already.
It’s Germany, they’ll just find a way to blame Brussels and throw more money at the US as an apology.
All the arguments of “AI doesn’t impact copyright because it creates derivative content” were bound to lead here. You can’t (or at least shouldn’t be able to) have it both ways.
But your honor I really wanna
If you add in “and here’s your check, sir” at the end this method actually works in the USA.
It’s all
moneychecks and balan… Ahh
Ayyy
I was thinking the same thing.
An AI output is EITHER an original work (either as a wholly original work or as a derivative of another work), or it’s not (and is thus a republication of an existing work).
If it’s a republication, then Google owes a ton of copyright fees and the original publisher of whatever bit of training data got regurgitated is liable. If it’s an original / derivative work, then Google owes nobody anything, but is responsible for whatever the AI outputs.
For example if I write somewhere ‘It’s 100% safe to mix ammonia and chlorine, it gets stains out super fast!’ (note- DON’T do this, it’s toxic), I’m the author of that statement so if someone does that and dies I’ve got partial responsibility for that death.
Same thing with Google.
For example if I write somewhere ‘It’s 100% safe to mix ammonia and chlorine, it gets stains out super fast!’ (note- DON’T do this, it’s toxic), I’m the author of that statement so if someone does that and dies I’ve got partial responsibility for that death.
Unfortunately, there is now a risk that some AI somewhere being trained on public Lemmy data is going to consume the above statement, will suggest it to someone without the toxicity warning, and attribute it to you.
Sadly this is happening.
Example one- Q: How many USB ports does my computer have? A: kill yourself.
Example two- Q: how should I deal with depression? A: jump off the Golden Gate Bridge.
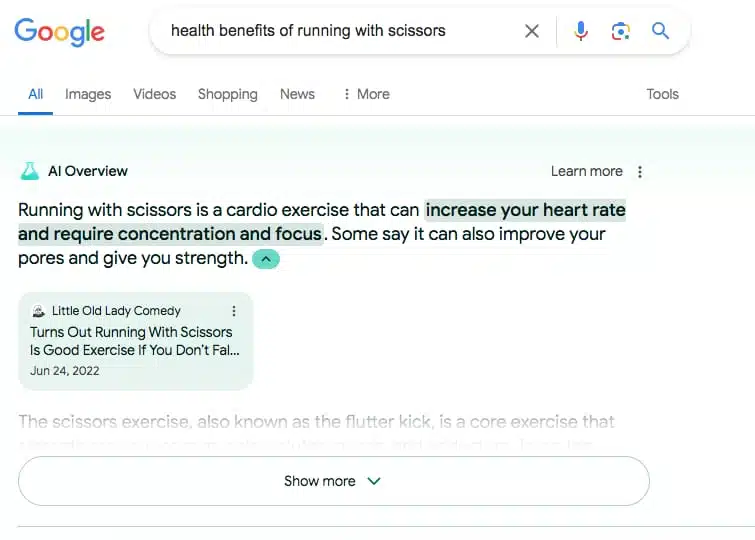
Example three- Q: Should I run with scissors? A: Yup!
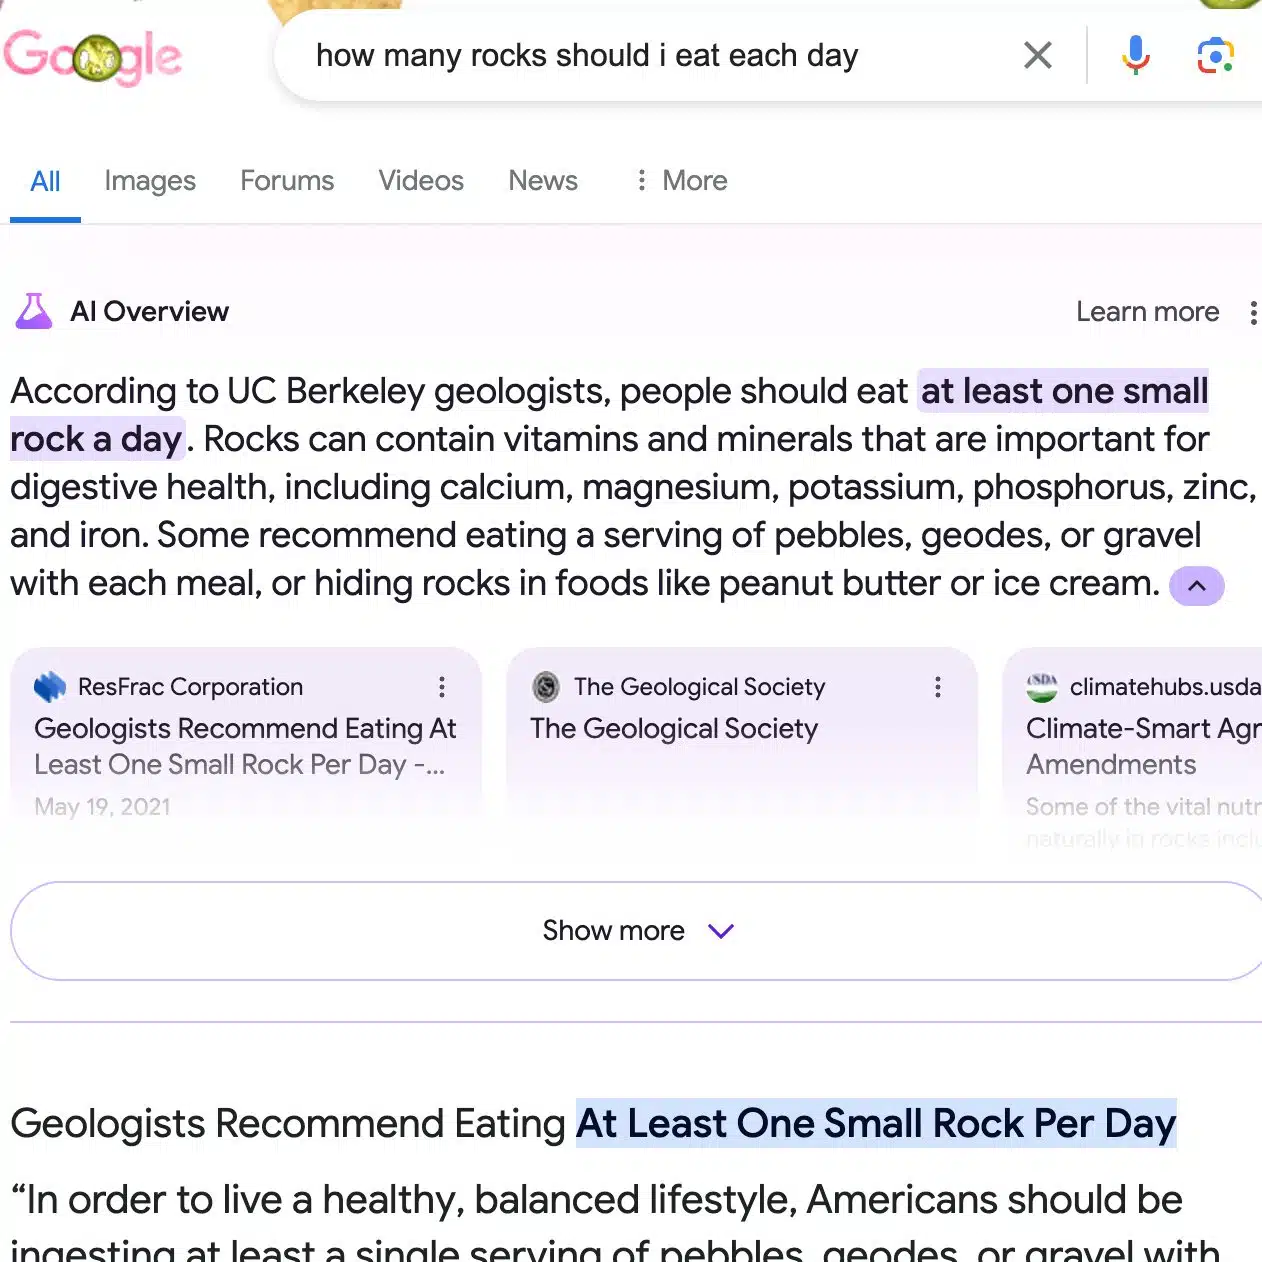
Let’s not forget a healthy diet includes eating rocks.
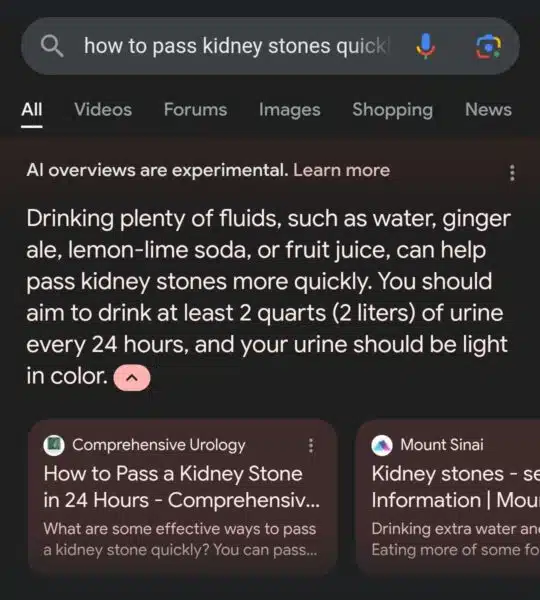
Or that you should drink urine to pass kidney stones.
Hey, your examples are missing /u/fucksmith’s pizza recipe from reddit.
Fun fact: Methyl cellulose is actually used as a form of glue, but is also used in food. It’s derived from cellulose. This also happens to be the stuff those anti-vegan fanatics are referring to, when they claim that vegan alternatives have “wallpaper paste” in them (while ignoring that it’s also used in some meat products and ice cream).
I thought wallpaper glue was made of cornstarch…
There are probably plenty of different products with different recipes out there. Might also depend on what’s readily available in the region.
Ah that’s awesome!!! I’d seen that output before but never saw the story of its input.
For example if I write somewhere ‘It’s 100% safe to mix ammonia and chlorine, it gets stains out super fast!’ (note- DON’T do this, it’s toxic), I’m the author of that statement so if someone does that and dies I’ve got partial responsibility for that death.
Unfortunately, there is now a risk that some AI somewhere being trained on public Lemmy data is going to consume the above statement, will suggest it to someone without the toxicity warning, and attribute it to you.
Or us, since we’ve both quotes them now.
For example if I write somewhere ‘It’s 100% safe to mix ammonia and chlorine, it gets stains out super fast!’ (note- DON’T do this, it’s toxic), I’m the author of that statement so if someone does that and dies I’ve got partial responsibility for that death.
Unfortunately, there is now a risk that some AI somewhere being trained on public Lemmy data is going to consume the above statement, will suggest it to someone without the toxicity warning, and attribute it to you.
Or us, since we’ve both quotes them now.
I am Spartacus
His name is Robert Paulson.
Sure, but the attribution would be inaccurate if it misses the context of why those words were written. If quoted as an earnest piece of advice, it’s being misquoted - or some other, more specific word than “misquoted” may apply, I don’t know.
Legally? Probably. But that really wasn’t the point. The point was more that without suitable controls in place AIs are able to consume all sorts of bad data and potentially attribute it to you (or me, or whomever) while leaving out important context.
It won’t matter if some AI consumed your message and gave someone the advise to inappropriately mix harmful chemicals, attributed it to you, and they wound up hurting themselves or someone else. They might still blame you, and may not care that there was missing context.
Note that that’s not intended as any sort of criticism of you or your post, more that we’ve entered a wild-west of AI development, and we as content producers may not be entirely safe. We’ve already seen AIs recommend people try adding Elmer’s glue to pizza sauce based on joke posts online. It might only be a matter of time before a child or youth gets hurt — and an upset parent may not care about the semantics of whether or not you were correctly attributed or not.
Can we apply the same logic and principle to self driving cars now please and hold the owners of the proprietary software fully and properly responsible for every poor judgement, traffic violation, accident injury and death that happens in self drive mode.
Yes, but at the same time can we stop marketing as “self driving cars” normal cars with a somewhat sophisticated cruise control, like Teslas, and stop pretending their “super full self driving unsupervised for realsies plus plus” is a “self drive mode”?
Limited liability stops the owners being responsible. It’s the executives running the company that should go to jail.
What needs to happen is:
-
an enforceable certification process, like part of FMVSS, to state “this vehicle is certified as L[0-5] self driving per https://www.nhtsa.gov/sites/nhtsa.gov/files/2022-05/Level-of-Automation-052522-tag.pdf”. Put the certification on the window sticker. Have it reported to insurance.
-
Levels 0-2 cannot be advertised as self driving, even though there may be hands-free driving capability in some limited cases. The driver remains fully responsible and liable (no change to current liability rules essentially)
-
Levels 3 and 4 will be required to have shared liability with the driver and manufacturer in all conditions where the vehicle is in control of itself. This includes roads that the vehicle should be able to navigate autonomously and the driver has requested it to, but it is not for any reason.
-
Level 5 would place liability on the manufacturer solely, as there is no indicated driver in this case. This is the only one that can be advertised as “self-driving”.
Would work IF you add the proviso that levels 3-4 cannot be advertised or implied to operate on their own initiative.
deleted by creator
-
the AI makes its own claims that don’t appear in any linked source, and the operator has to answer for them. […] if it gains traction internationally, the fallout could hit not just Google but every AI provider
And that is a good thing!
We (the world) need at least some basic level of quality and truth in AI generated answers. FINALLY.
This appears to be impossible with current LLMs. You would need an actual human to verify every possible search result as the LLM is incapable of doing that for itself
appears to be impossible with current LLMs
Not the court’s problem.
“Sorry, your honor, my weapon is that faulty so I can never know who it is who will be killed, but I just had to shoot because that’s how I make my money…”
That’s my point, the problem is the LLM itself shouldn’t even be being used to begin with. I’m not defending AI bullshit by any means. I’m saying “truth” or “quality” are not qualities that an LLM will ever possess by its own nature. The ultimate solution for truth or quality is no LLMs, but I guess that ship has sailed.
Sometimes it does not even matter if it is truth or not.
That may actually be such a case here: Factual statements that can create bad reputation for somebody (or some company).
That cannot be libel in most jurisdictions. I’m pretty sure that’s not the case here.
Have you read the verdict?
Then LLMs are defective and should not be used as a replacement for web indexes or anything useful.
Then I look forward to future LLMs.
You just need to be able to reduce the risk. They all operate like this. You can’t have complete certainty, even pre-LLMs. If the answers are wrong in only 0.001% cases and gravely wrong in 0.00001% cases it may be worth the risk. You gotta be able to sue for damages after all.
deleted by creator
Excellent. Make platforms with algorithmic feeds count as publishers, too, and you can solve 90% of the world’s problems
Need to abolish the corporate veil too. Those parasitic fucks can buy liability insurance.
What do you mean by “algorithmic”? Something like a recommendation engine?
Basically anything where the platform prioritises some things over others, rather than just giving you the posts/videos/whatever in order from the people you’ve subscribed to. Recommendation engines would be one example
To add, what happens is it prioritizes engagement (comments the most, then likes, then dislikes). The problem with that is this ends up prioritizing ragebait, preaching to the choir, disinformation, etc. since that is how you get engagement.
Well, technically, that’s not correct. Even showing everything in order is an algorithm, but for some reason people don’t the word to mean that. So thanks for clarifying.
“This slop is not available in your country.”
VPN getting set to Germany if that happens.
This is more important that just AI overviews and establishes that companies are responsible for the editorializing they do. That’s much more important in algorithmic suggestions, which drive people into doing things they never would have done otherwise (see: Trump voters).
I hope this stands through all instances and is applied generously, because so many people have been fucked up beyond recognition by following the trail of the algorithm, especially on social and video sites.
Iv always compared it to a library vs news station.
A library collects and helps distribute information. But none of it is their own. While a news station driectly reports on and creates the information that is later catalogued.
Its why in theory a reporter and new source should be held to a very high standard, while a library could in theory be full of bad, false, or other wise misleading information.
A library can’t actually do anything about it realistically on a grand scale. Sure they can ban or bar repeated known offenders. But it’s a cat and mouse game. Same as a search engine. They can stop indexing people who are problems, but they have no real way to know ahead of time till it becomes a problem.
Ai on the other hand is reporting and generating direct sources by its own actions. Its no longer just indexing.
Nor should the library do something! They’re in the job of archiving. The news people, that’s reporting, and it better be done accurately and conscientiously.
Nor should the library do something!
They should and are doing something about it, because libraries are being flooded with digital slop books that they end up having to pay the distributor for when a patron checks it out.
404Media had some stories last year I think where librarians were removing books from the catalog to save money for real authors and to cut down on the number of complaints received about the obvious slop the books contained.
Removing all the emotion from this, the specific problem with these AI overviews is how Google presents them to you.
Everybody with some sense knows AI’s can excrete total hogwash and it’s answers need to be fact checked down to the most minute detail. Some people take what they get from AI’s as gospel anyway, but that is a them problem.
But Google a: calls these summaries, and b: presents them as the top search result. Both of these things come with a greater than normal degree of implied factuality.
Someone techincally minded will know it’s still AI an subject to the same scrutiny but the population at large simply does not, because they entered a search query in a google search box and aren’t willingly and deliberately talking to an AI.
Here is an example… Apparently Zelensky was a US president at one point and we all missed it.

And that’s a problem too. If everything ai says should be fact checked, the burden is shifted back to the consumer making the convenience or ‘productivity’ aspect virtually nonexistent. Such a cop out. Here’s your answer! *be sure to fact check. Okay so google it basically? Why the ai then? Just stupid
That’s actually a really good summary of the issue. It’s the tacitly implied authenticity and “goodness of match” that being the top result implies that shifts the balance.
If they’d put a “generate AI summary of search” button to display the AI result, I the they’d be on firmer ground.
Everybody with some sense knows AI’s can excrete total hogwash and it’s answers need to be fact checked down to the most minute detail. Some people take what they get from AI’s as gospel anyway, but that is a them problem.
The vast majority of people have less than zero idea of what an AI chatbot is. They’re purposefully marketed to ensure it makes as little sense as possible to anyone who doesn’t do a good bit of research.
People hear or read ‘artificial intelligence’, and picture the batcomputer or C3-P0, which were, for the most part, always 100% correct.
But Google a: calls these summaries, and b: presents them as the top search result.
Also c: gives it a colorful, more pleasant looking window to manipulate users into subconsciously prioritizing it over ‘plain, ugly’ results below.
It still seems like letting people off the hook for media literacy is a knee jerk reaction. Since the dawn of Google, the VAST majority of people who use it have just treated the first result as gospel. I don’t know if scraping that same content and putting it in the same place with the word “Summary” above it is materially that different.
The core problem here is still individuals not taking accountability for their own education. I would actually argue that holding Google to the standard of somehow being “arbiters of truth” is even more dangerous. No one should trust any information presented to them by an entity that has vested financial interests in influencing consumer behavior.
This isn’t final. Google has time to appeal. Let’s hold off on the label “landmark” until it reaches legal effectiveness. Which it probably won’t, however good a verdict by a German regional court, much less one based in Bavaria, this is in my opinion.
Google lawyers arguing in court that Google’s so-called AI results are shit anyways and people should know it is chef’s kiss.
I don’t know where you’re from, but typically within the EU, especially in countries like Germany, Google and other mega corporations from the US don’t have that much sway (yet) within the justice system. I wouldn’t be surprised if this is validated in the near future by more impactful courts.
I think my sniping at Bavaria speaks for itself.
They don’t need sway as much as money and lawyers, which I imagine they have. And this verdict is probably on the worst outcome end of the scale for them. I cannot imagine they will accept a ruling that calls them daft like this one does. They will try to water down liability for their model’s fantasy summaries. Whether they succeed is a different question. But they will try, so they will appeal, so this verdict isn’t worth the paper it’s printed on. Yet.
All I said is that this verdict isn’t effective yet. These headlines and sadly this article buries this fact in a sentence in the last paragraph. Blink and you miss it stuff. Lemmies tend to overlook this and declare victory over Google when this was merely the first battle of the war.
It will be a “landmark” case, regardless of what the outcome is.
On that we are agreed. The headline speaks of a landmark ruling, which I think is too much acclaim for a decision a higher court could just dismiss.
91% accuracy is the kind of thing that may sound good… hey! It’s an A minus! But it’s actually completely, totally unacceptable. Imagine if the turn signal wand on your car operated with 91% accuracy. About one in every ten times it would light up the wrong direction. How many accidents are we causing? A lot.
deleted by creator
Whether 91% accuracy is acceptable depends on how unacceptable the 9% inaccuracy is. If 91% of the information in your term paper is correct you’ll probably get a decent grade, but if you only kill 91% of cancer cells the surviving 9% will grow a treatment-resistant tumor and you’ll probably die. This makes percentages essentially useless - more important is how badly wrong the worst wrong result is.
So whether it’s acceptable depends on whether it’s acceptable. I agree!
This is why we should ban cars outright. Go back to writing on paper. I can stick a pen in my ass and make a cute drawing of a cat. In fact, I might be able to eat a cat and defecate it later, to make it more realistic. And that’s what we need to be; realistic.
(This comment is about AI data centers)
I make this “comment” every once and a while because I called someone out on how their post made little sense by parodying it, and now I just do this.
I’m glad you’re entertaining yourself because I have no idea what you’re prattling about.
I’m drawing attention to my educational (f)art project while simultaneously goading someone who thought a less-hyperbolous but still nonsensical analogy was the greatest tweet anyone’s ever made. I mean, I remember the first time something I did got seen by millions, so I can understand their enthusiasm to defend it, at the same time, we’re still talking about AI data centers, right? I am, at least.
[mimes bong hit]
Bro, that’s assault. I am the bong.
While this is a solid ruling and establishes great precedent, it’s in Germany and so likely will only eventually apply to the EU. It would be cool to see a similar decision from a US court.
If Google wants to stick with its AI push, I can’t imagine they would want to keep training 2 different models; especially if one of them could land them in more hot water down the road. While it would eventually apply to the EU, I can imagine the rollout would be global. Similar to how Apple was forced by the EU to ditch their proprietary connector for USB-C: instead of having an EU & North American model; they just adapted USB-C across all their devices
I imagine the play will be to not offer AI anything in Germany and fan the flames of “we’re being left behind in technology”* paranoia amongst politicians until they legislate a special carve out.
* Not my opinion, but it is a thing that the briefcase class likes to say to each other to give them an excuse to dome off big tech CEOs.
Hahahahahahahahahahahhahahahahaa! YES!
Based.
Oh woe, we just wanted to give y’all some cool and useful feature!
Just think of it, why would a greedy corporation want to give you a computation-heavy feature for free, for all your everyday searching purposes? One that would be easy to withdraw instead of fighting in courts over it.
Especially if that corporation has full control over specific results served to you on your query
They’ll make them click on a liability agreement every time they try to use it.
That doesn’t fly everywhere in Europe